data annotation

annotation company, annotationservices, data annotation services

How Annotation Support Helps AI Teams Build High-Quality Evaluation Datasets?

Just like anything else that can be improved by measurement, there are examples of AI teams that can also make use of an evaluation dataset—the gathered, labelled, real-world examples practitioners use to assess if their model is accurate, safe and effective in the real world. Yet many teams treat evaluation data as an afterthought, a spreadsheet assembled in a hurry the week before launch. This is a hazardous throw. With a poor set of evaluation data, it could seem as if a poor model is good, and a good model is poor. At Annotation Support, we work with AI teams every day to build evaluation data they can trust. Here is how dedicated annotation service makes the difference. Why Evaluation Data Demands a Higher Bar? Training is likely to be a type of volume/ variety training. Information consisted of assessment information that is linked to accuracy and belief. The key to them is deciding when to move products out of their lines, what to optimize and which models to use. That raises the standard in three ways: Most in house teams are unlikely to be able to provide all three, during a shipping product. This is where the Annotation partner comes in handy… 1. We Turn Fuzzy Goals into Clear Guidelines The most typical reason why the evaluation information is bad is not the bad annotators. It’s vague instructions. What is an appropriate answer? What will be the answer where part of it is correct? In what ways can something that isn’t hurtful become hurtful? Here Annotation support collaborates with your team to convert these questions to clear and measurable direction. These involves piloting the rubric and making any “difficult cases” visible; then refining the rubric to ensure that all of the annotators understand it in the same way. You have a labelling standard documented, accessible (repeatable) and can be audited easily. 2. We Match Trained Specialists to Your Domain General crowd labelling works for simple tasks, but modern evaluation often demands more. For medical report evaluation, part of legal name clause extraction, code completion or for a multilingual conversation, intelligent individuals are necessary. Our services include recruiting, training and verifying the staff member(s) you need: linguists for multilingual evaluation needs; domain experts for specific subject expert knowledge; engineers for code review. That skill is taken on by the quality of the label, especially on the unmodelled subtle cases. 3. We Build Quality Control into Every Stage It is unfeasible that good evaluations sets are likely to be found in one “pass”. Our workflows sprinkle quality checks throughout: This turns labelling into a process rather than an event and is something which can be factored in and reported on as you are doing it. 4. We Help You Cover Edge Cases and Failure Modes In some production contexts a model that scores well on the test sets to which it was given may not perform well. Usually the ‘long tailed’ – queries with no real structure, bad form, unfamiliar language, uncommon purpose or format. We help you to formulate a purposeful but balanced assessment system that is intentionally filled with such challenging items as well as ways to facilitate “red teaming” sessions where the annotators knowingly develop items that are to be more difficult and/or identify items as challenging items. This gives you a testing set where all that you get is along the lines of where your model fails on average, as well as where it fails. 5. We Welcome Modern Assessment Practices Evaluation no longer only categorises something. Our team members will replace human judgment in the following aspects: Such are judgment calls and labour-intensive tasks. They can be set up to operate on a regular basis and scaled by having the tooling, workflows and trained reviewers brought to them. 6. We Scale with Your Roadmap. Evaluation Needs are typically not constant. When you complete your major upgrade on your model, you could be needing 500 examples for the month, and 20,000 examples for next quarter. In-house labelling teams may be slow and expensive to the tune of that much turnover to achieve one of their fastest and most cost-effective solutions. We’re a managed partner, in the sense that we increase or decrease capacity within a relatively short amount of time, we have a fairly predictable turnaround and we’ve the same standard of quality in volume as we have in small quantity. Your ML engineers are mainly involved in the whole modelling stuff and not recruitment and training of your labellers and supervising them. 7. You Get Faster Iteration and Better Decisions The effective outcome is a quick confident pace. With reliable evaluation data, your team can: Shorter is better feedback time, better is reliable evaluation. When there’s a question as to the believability of a metric, your team can act on it, rather than debate it. Let’s Build Your Evaluation Dataset Together An evaluation dataset is only as good as the people and processes behind it. At Annotation Support, we pair clear guidelines, skilled reviewers, rigorous quality control, and the capacity to match your roadmap to help AI teams get metrics they can trust and models they can ship with confidence. If evaluation data is holding your team back, the fix may not be a better model. It may be better labels. Visit annotationsupport.com to talk through your evaluation needs or request a pilot batch.
artificial intelligence, data annotation services

Data Annotation for Foundation Models: Enabling Next-Gen AI Capabilities

The era of Artificial Intelligence has taken a new turn with the advent of **foundation models** which are large scale AI models that can comprehend text, images, audio, video, and even multimodal data. Industries are revolutionized by the advent of these models, which fuel intelligent applications from virtual assistants to autonomous vehicles, all the way to medical diagnostics. From virtual assistants to autonomous vehicles to medical diagnostics, Large Language Models (LLMs), Vision-Language Models (VLMs), and multimodal AI are driving intelligent applications that are transforming industries. But there is one crucial component that makes these models truly intelligent: the quality of the data annotation. To learn patterns, relationships and context, foundation models must be trained with billions of accurate data points. Even the most sophisticated AI systems can fall short of providing precise, safe, and trustworthy outputs without reliable annotations. In this blog, we will delve into the significance of data annotation for foundation models, the methods employed in data annotation, and the role professional data annotation services play in creating next-generation AI solutions for organizations. What are foundation models? Foundation models are massively trained AI systems that are capable of being fine-tuned for a range of tasks below. Organizations can fine-tune foundation models to apply them to distinct use cases and industries rather than creating and training distinct AI models for each application. Examples include: These models are trained on a variety of data sources, and the quality and consistency of annotated data are crucial for effective training. Why Data Annotation Matters for Foundation Models? Foundation models need to be capable of comprehending context, relationships, intent, and complex real-world situations, unlike traditional machine learning models which are designed to handle specific tasks. By creating accurate annotation, models can: The more well annotated the better the model works in various applications. Types of Data Annotation Used in Foundation Models 1. Text Annotation Through textual annotation, the language models can grasp grammatical rules, meaning, context, and semantics. The most common annotations are: Applications include: 2. Image Annotation For computer vision foundation models to identify objects and environments in a picture, they need millions of labelled images. Popular methods of annotation are: Applications include: 3. Video Annotation Video Datasets enhance foundation models in comprehending motion dynamics, activities, and temporal relationships. Annotation methods include: Applications include: 4. Audio Annotation Speech and audio annotation enhances voice recognition and conversational AI. Tasks include: Applications include: 5. Multimodal Annotation Modern Foundation models integrate several data types at the same time. Multimodal annotation links: These datasets allow AI systems to comprehend information in various modalities. Best Practices for Foundation Model Annotation To enhance the quality of the annotations, the following best practices are recommended: Why Choose Annotation Support? We offer scalable, enterprise-grade data annotation services to support foundation model development at Annotation Support. We have specialized teams to annotate images, videos, text, audio and multimodal data to provide high quality training data for cutting edge AI applications. Conclusion While foundation models are changing what AI can achieve, they need high-quality data to learn and become effective. The context these models need to understand language, images, video, and audio, as well as complex multimodal interactions of those modalities with one another, is provided by accurate, consistent, and scalable data annotation. The collaboration with an experienced provider of annotations such as Annotation Support allows organizations to speed up the development of their AI and enhance its accuracy and effectiveness, thereby helping them create the next generation of intelligent applications with tangible business impact.

annotation company, data annotation services, data labelling annotation

Improving Customer Experience with Annotated Data

Our society is digital, and experience customer is a factor that is distinguishing businesses today. Knowing more about your customer enables you to step up your game and provide faster, more personalized and more meaningful interactions. A data-annotated foundation is the base for AI-powered customer insights and automation, which is one of the most impactful, yet underutilized aspects of incredible CX. What is Annotated Data? Annotated Data is raw data (text, images, audio, or video) that has been labeled to give meaning to AI and machine learning models. Annotation enables systems to comprehend for customer experience: Why Annotated Data Matters for Customer Experience? Without annotations, AI systems won’t be able to correctly understand customer interactions. Quality annotated data makes possible: Types of Annotation Used in Customer Experience 1. Text Annotation Provides names for customer e-mail, chat logs and feedback. Examples: 2. Audio Annotation Analyzes voice interactions in call centers. Examples: 3. Image Annotation Utilized when interacting with customers by visual means. Examples: 4. Video Annotation Assists in analysing the behaviour of customers in the physical environment. Examples: How Annotated Data Improves Customer Experience? 1. Personalization at Scale By using annotated data, AI systems can grasp customer preferences and provide personalized content, offers, and recommendations. 2. Smarter Chatbots and Virtual Assistants Chatbots can with proper labeling of the datasets : 3. Sentiment Analysis for Better Engagement With annotation, a company can find out if a customer is happy, frustrated or dissatisfied and take action accordingly. 4. Faster and More Accurate Support Annotated data can be used to train AI models, which enable them to: 5. Proactive Customer Support Annotated datasets allow the prediction of issues to stem from before the problem becomes too large and proactive outreach is made possible. Real-World Use Cases Challenges in Using Annotated Data Best Practices for Leveraging Annotated Data Role of Professional Annotation Services Outsourcing annotation services helps businesses: Annotation Support provides customized annotation solutions to enhance customer experience through AI-driven insights. Conclusion Data is the foundation of today’s customer experience strategies and it needs to be annotated. It allows businesses to know their customers intimately, provide feasible replies and offer customised experience on a large scale. Investing in quality annotation is not only about enhancing AI but about creating more impactful, meaningful customer relations.

data annotation services, keypoint annotation

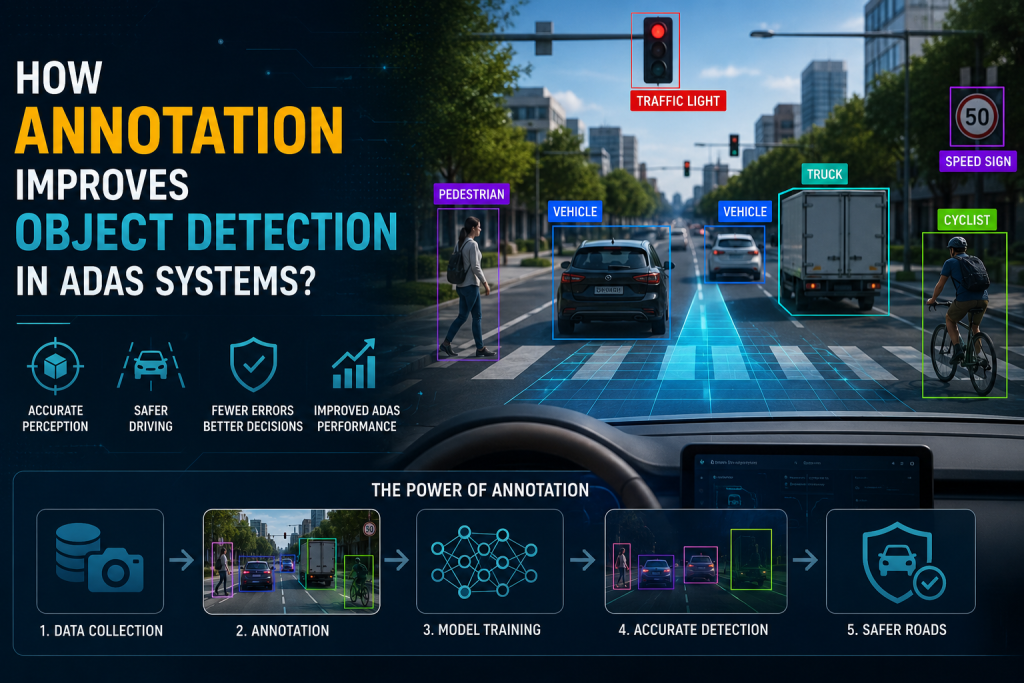
How Annotation Improves Object Detection in ADAS Systems?

Advanced driver assistance systems (ADAS) are a revolution in automobiles that offer improvements in safety, error reduction from human factors, as well as semi-autonomous driving. But at the heart of these intelligent systems is a single crucial component: high-quality data annotation. Correct annotation directly influences the reliability of ADAS model object recognition, e.g. pedestrian, vehicles, lane marking, traffic sign etc., and reaction to the objects. What is Object Detection in ADAS? In the context of ADAS, object detection is the process of identifying, categorizing, and tracking objects in real time using data from cameras, LiDAR, radar, and other sensors and AI models. They supply energy for functions such as: Role of Annotation for ADAS Annotation involves human input of raw data from sensors to label the data, which takes it one step closer to the machine learning models able to learn patterns and make decisions. Even the best AI models will fail to perform well without accurate annotation. Different Types of Annotation for ADAS Applications 1. Bounding Box Annotation Can be used to detect cars, pedestrians, cyclists and animals. Impact: Assists users in finding and categorising quickly multiple objects in real time. 2. Semantic Segmentation Annotates each image pixel in an image (road, sidewalk, vehicle, sky, etc.). Impact: Allows for accurate scene understanding and road detectability. 3. Instance Segmentation Discerns and discriminates between two or more similar from a class. Impact: Important for dispatching several cars and/or persons. 4. Polygon Annotation Maintains the ability to capture shapes which are not regular such as lane markings and the road boundary. Impact: Better Lane Detection and Road Edge Recognition. 5. Keypoint Annotation Indicates locations like corners of vehicles or pedestrian crossings. Impact: Useful for motion prediction and behavior analysis. 6. LiDAR (3D) Annotation Labels 3D data point clouds for depth and spatial awareness. Impact: Enhances distance estimation and collision avoidance. How Annotation Improves Object Detection? 1. Increases Model Accuracy Annotated data enables AI models to develop proper object boundaries, shape, and classification. 2. Enhances Real-Time Decision Making Improved labelling facilitates rapid detection and action, essential in safety-critical situations. 3. Reduces False Positives and Negatives Good annotation helps to reduce errors such as: 4. Enhances Edge Case Performance Models are made more robust when they are trained on annotated datasets which have a wide variety of scenarios (rain, fog, night driving etc.). 5. Allows Improved Sensor Fusion Overall consistent annotation of the camera, LiDAR and radar data aids in multi-sensor integration. Importance of High-Quality Annotation All annotation is not created equal. Labeling can sometimes be quite poor, causing nasty results in an ADAS system. Key Quality Factors: Challenges in ADAS Annotation Best Practices for ADAS Annotation Real-World Impact ADAS systems can be, with the help of high quality annotation: Conclusion For effective object detection in ADAS systems, the bases are annotations. Labelled data directly impacts the vehicle’s ability to correctly and safely understand the world around it. Investing in high-quality annotation is not just a technical necessity—it’s a critical step toward building safer roads and more reliable autonomous driving systems.

data annotation services, human-in-the-loop

Manual vs Automated Data Annotation: Pros, Cons, and Use Cases

Data annotation is essential for training AI models, but one big question organizations face is: Is it better to use humans, automation or both? This question is dependent on the complexity of your project, level of accuracy, budget, and schedule. This knowledge allows you to design the correct workflow by knowing all the weaknesses and limitations of manual and automated annotation. What is Manual Data Annotation? Human annotators do the manual annotation whereby the data are assigned labels according to guidelines and domain knowledge. It is the classical method and is crucial in cases of high accuracy AI systems.  Pros of Manual Annotation Cons of Manual Annotation Best Use Cases  What Is Automated Data Annotation? Automated data annotation involves the pre-labeling, or fully labeling of data with little human assistance or AI models, scripts, or tools. Pros of Automated Annotation  Cons of Automated Annotation Best Use Cases (Best of Both Worlds): The Hybrid Approach. Certainly, the costs of today AI pipelines are comprised of a combination of both approaches: Speed is processed by automation → Accuracy of humankind. Workflow example: This saves money and time as well as preserving quality. Comparison at a Glance Factor Manual Annotation Automated Annotation Speed Slow-Moderate Very fast Cost Higher Lower Accuracy High (complex tasks) Moderate Scalability Limited by workforce Highly scalable Edge Case Handling Strong Weak Best For Complex, domain-specific data High-volume, repetitive data How to Choose the Right Approach? Ask these questions: Final Thoughts Annotation is increased with automation. Humans make it reliable. Instead of this, the most successful AI teams do not work with either but set up AI-assisted human-in-the-loop pipelines that strike the optimal equilibrium between efficiency and precision.

Scroll to Top